Agile Data Science
  • Posts
  • Projects
  • Author
  • Github

Agile Data Science

Practical writing on statistics, data science, machine learning and reliable software, by Maciej Nasiński.

Statistics · Software · Open source

Practical data science, thoughtfully built

I’m Maciej Nasiński. I write about statistics, machine learning, AI, and building reliable software with R and Python.

Browse the posts Explore projects

Portrait of Maciej Nasiński

Latest writing

Recent articles on machine learning, statistical graphics and building AI-assisted software.

Kumo-Tabular vs XGBoost, CatBoost and LDA: Does Feature Engineering Still Matter?

A small benchmark compares pretrained Kumo-Tabular with tuned boosting and standardized LDA, with and without domain-inspired features.

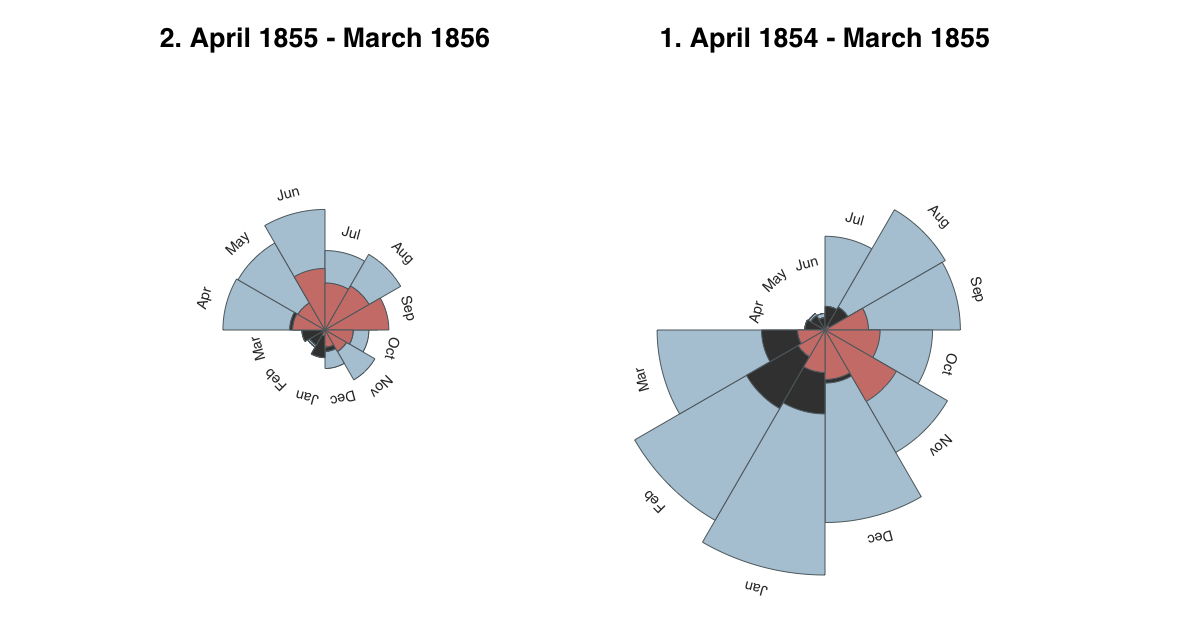
England and Her Soldiers (1859): The Book That Made Statistics Visual

Florence Nightingale’s rose diagram in an 1859 copy of England and Her Soldiers: what it shows, what it cannot prove, and how to recreate it in R.

Agents Are Easy. Products Are Still Hard.

Lessons from delivering AI-assisted statistical-programming products: why AI agents make working code easy but the right product is still hard, with a gridify case study.

Are Em Dashes Really Suspicious? A Gutenberg Top-100 Check

Are em dashes a sign of AI-generated text? A Python analysis of 100 top Project Gutenberg books finds em dashes in every book once double hyphens are counted.

R Package Downloads: Why CRAN Counts Are Proxies and What to Measure Instead

There is no global CRAN download count. What cranlogs measures and misses, how to get proxy counts in R, and better metrics for R package usage.

Understanding LLMs and Transformers: A Deep Dive into Modern AI

How Transformers and large language models work, encoders versus decoders, and what you learn in the free Hugging Face LLM course, with pipeline examples.

Vibe Coding: Adopting the Exponential Future of AI-Assisted Development

A practical approach to vibe coding with AI assistants: modular design, test-driven validation, recommended tools and models, and what to do when it goes wrong.

Visual Studio Code: Toolkit for Data Scientists

Why Visual Studio Code is a complete toolkit for data scientists: Python and R extensions, GitHub Copilot, settings as code and reproducible devcontainers.

GLM Residuals in R: Pearson, Deviance and Quantile Residual Diagnostics

A practical guide to residual diagnostics for logistic and Poisson GLMs in R: raw, Pearson, deviance and quantile residuals, and how to spot misspecification.

Curse of Dimensionality: Lessons from the U.S. Air Force Cockpit Design

Why no U.S. Air Force pilot was average: the 1950s cockpit study as a lesson in the curse of dimensionality, with a multivariate normal simulation in R.

Open Source: Given enough eyeballs, all bugs are shallow

What open source means, how projects like Linux work, common open source licenses, governance models, and the different ways you can contribute.

Mermaid Diagrams in Markdown: Flowcharts, Sequence Diagrams and Gantt Charts

How to create flowcharts, sequence diagrams, Gantt charts and Sankey diagrams with Mermaid in Markdown, plus tools, alternatives and help from LLMs.

WebAssembly for Data Science: webR, Pyodide and Shinylive in the Browser

How WebAssembly runs R and Python in the browser at near-native speed, and how webR, Pyodide, Shinylive and Quarto use it for interactive data science.

Python Enhancement Proposals (PEPs)

What Python Enhancement Proposals (PEPs) are, how the PEP process works, and the PEPs that shaped Python: PEP 8, PEP 20, PEP 484, PEP 572 and PEP 621.

Object-Oriented Programming for Data Science Developers [In-Depth]

An in-depth guide to object-oriented programming for data science developers, with classes and design patterns from scikit-learn and pandas in Python.

Containers for Data Scientists [In-Depth]

An in-depth guide to Docker, Podman and Apptainer containers for data scientists: Dockerfiles, images, CLI commands and reproducible R and Python environments.

Conjugate Priors: Harnessing Closed-Form Solutions in Bayesian Inference

Conjugate priors give closed-form Bayesian posteriors. Beta–Binomial, Gamma–Poisson and Normal–Normal examples in R show how beliefs update with data.

Bernstein–von Mises: Bridging Bayesian and Frequentist Worlds

How the Bernstein–von Mises theorem links Bayesian posteriors and frequentist confidence intervals in large samples, with a worked Normal–Normal example in R.

Celebrating a Classic: “How R Searches and Finds Stuff” by Suraj Gupta

Why Suraj Gupta’s How R Searches and Finds Stuff is still essential reading for understanding R environments, namespaces and scoping rules.

Graph Databases and GQL: An Introduction to the ISO Graph Query Language

An introduction to graph databases, property graphs versus RDF, common use cases and tools, and GQL, the new ISO standard query language for graphs.

Scrum: Just a Framework, Agile: A General Philosophy

Agile is a philosophy and Scrum is one framework for it. A guide to the Agile Manifesto, its twelve principles, and applying Agile beyond Scrum.

Exploring the Tinyverse: A New Standard in R Package Development

The tinyverse approach to R package development: why minimal dependencies improve stability, how it compares with the tidyverse, and how to reduce dependencies.

Stack Overflow Developer Survey Insights for Strategic Tech Planning

How to use the annual Stack Overflow Developer Survey for strategic tech planning: reading the demographics, following trends and spotting rising technologies.

ggcall: Transparent R Packages with ggplot2

ggcall makes ggplot2 code reproducible inside R packages by recording the plot-building call, using metaprogramming to override ggplot() and the + operator.

GitHub Codespaces: Cloud Development Environments for R and Python

How GitHub Codespaces provides ready-to-use cloud development environments, how .devcontainer files keep setups consistent, and example R and Python codespaces.

Pre-commit Hooks for R and Python Projects

How to set up pre-commit hooks for R and Python projects to run linters and checks before every Git commit, including automated fixes with pre-commit.ci.

GitHub Student Developer Pack: Learn to ship software like a pro

What the free GitHub Student Developer Pack and Teacher Pack include, such as Copilot, Codespaces and GitKraken, and how students and educators can get them.

Analyzing the Kasa Romana Lottery with Knapsack Algorithm [Updated]

An R knapsack analysis and a modular arithmetic proof show that no subset of 1,002 sampled Kasa Romana coupons reaches the tested targets of 100 to 1,000.

Moving Beyond P-Values in Scientific Research: Insights from the ASA Statement and Frank Harrell

Why the ASA statement and Frank Harrell call for moving beyond p-values, and why effect sizes and confidence intervals should be reported alongside them.

Why Git is Here to Stay

Why Git remains the standard for version control, the fewer than 20 commands you need, CLI versus GUI tools, and how Git differs from GitHub.

No matching items

    Browse all posts →

    Selected projects

    The Best Pharma Table

    My winning 2025 Posit Table Contest entry, recognised as The Best Pharma Table.

    Educational Story Outcome Predictor

    A fine-tuned DistilBERT model for classifying educational story annotations.
    Explore all projects →